Methods › General › Stochastic Optimization › SGD with Momentum
SGD with Momentum
archive 2025-07-28 Description, source and code snippet are the archive's method entry.
Why SGD with Momentum?
In deep learning, we have used stochastic gradient descent as one of the optimizers because at the end we will find the minimum weight and bias at which the model loss is lowest. In the SGD we have some issues in which the SGD does not work perfectly because in deep learning we got a non-convex cost function graph and if use the simple SGD then it leads to low performance. There are 3 main reasons why it does not work:
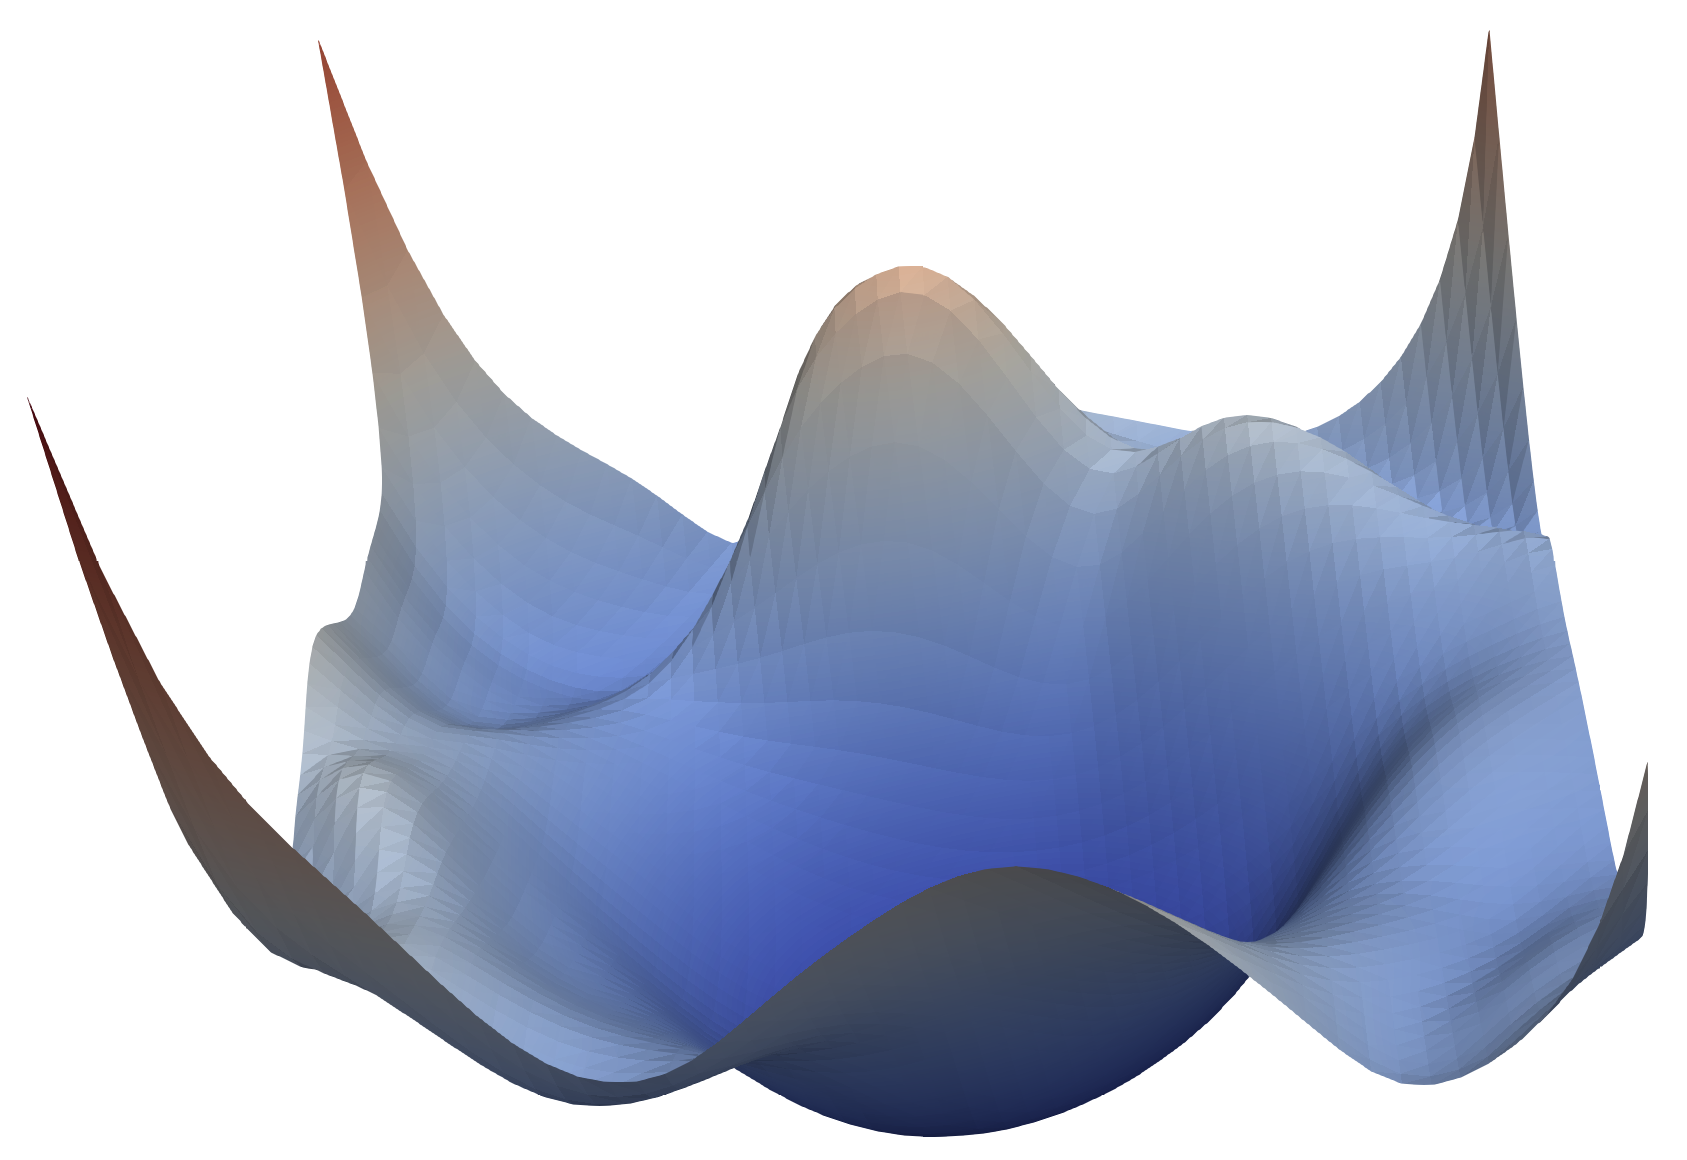
1) We end up in local minima and not able to reach global minima At the start, we randomly start at some point and we are going to end up at the local minimum and not able to reach the global minimum.
2) Saddle Point will be the stop for reaching global minima A saddle point is a point where in one direction the surface goes in the upward direction and in another direction it goes downwards. So that the slope is changing very gradually so the speed of changing is going to slow and as result, the training also going to slow.
3) High curvature can be a reason The larger radius leads to low curvature and vice-versa. It will be difficult to traverse in the large curvature which was generally high in non-convex optimization. By using the SGD with Momentum optimizer we can overcome the problems like high curvature, consistent gradient, and noisy gradient.
What is SGD with Momentum?
SGD with Momentum is an optimization technique designed to improve the performance of neural networks. To understand the intuition behind it, consider the analogy of a ball rolling down a slope. As it rolls, the ball gains speed over time due to momentum.
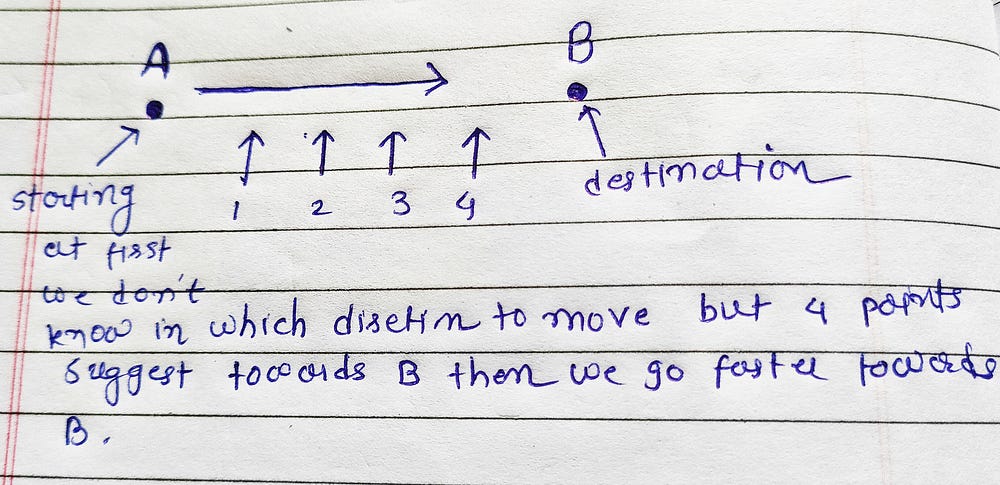
Suppose we have a starting point A and want to reach B. If we are uncertain about the correct direction, we can ask four other points that have already reached B. If all four indicate the same direction, we can move more confidently and at a faster pace. This is the key idea behind SGD with Momentum.
How does SGD with Momentum work?
To understand its working, we must first explore the concept of the Exponentially Weighted Moving Average (EWMA), a technique used to identify trends in time-series data. The formula for EWMA is:
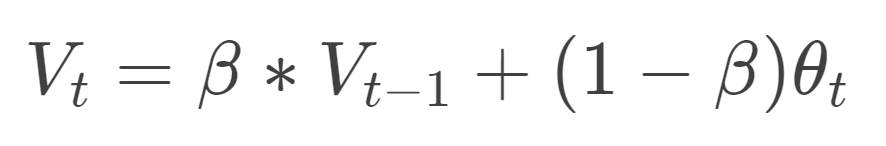
In the formula, β represents the weightage that is going to assign to the past values of the gradient. The values of β is from 0 < β < 1. If the value of the beta is 0.5 then it means that the 1/1–0.5 = 2 so it represents that the calculated average was from the previous 2 readings.
The value of Vt depends on β. The higher the value of β the more we try to get an average of more past data and vice-versa. For example, let's take the value of β 0.98 and 0.5 for two different scenarios so if we do 1/1-β then we get 50 and 10 respectively so it was clear that to calculate the average we take past 50 and 10 outcomes respectively for both cases. Now in SGD with Momentum, we use the same concept of EWMA. Here we introduce the term velocity v which is used to denote the change in the gradient to get to the global minima. The change in the weights is denoted by the formula:
the β part of the V formula denotes and is useful to compute the confidence or we can say the past velocity for calculating Vt we have to calculate Vt-1 and for calculating Vt-1 we have to calculate Vt-2 and likewise. So we are using the history of velocity to calculate the momentum and this is the part that provides acceleration to the formula.
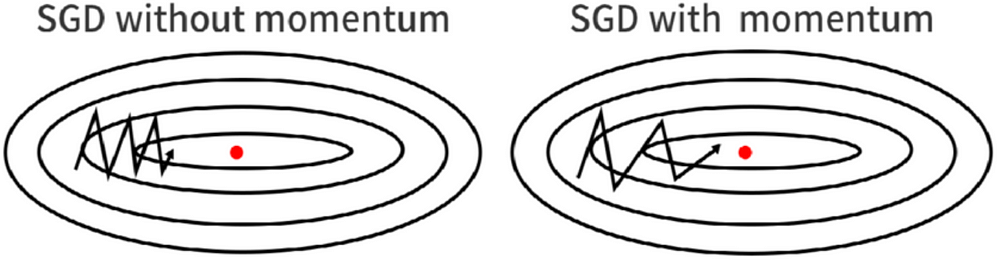
Here we have to consider two cases: 1. β=0 then, as per the formula weight updating is going to just work as a Stochastic gradient descent. Here we called β a decaying factor because it is defining the speed of past velocity.
- β=1 then, there will be no decay. It involves the dynamic equilibrium which is not desired so we generally use the value of β like 0.9,0.99or 0.5 only.
Advantages of SGD with Momentum
- Faster Convergence: Momentum accelerates training, making it faster than standard SGD.
- Escaping Local Minima: Momentum helps the optimizer overcome small local minima and reach the global minimum.
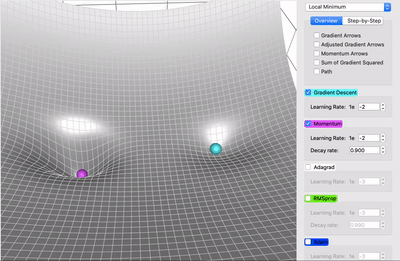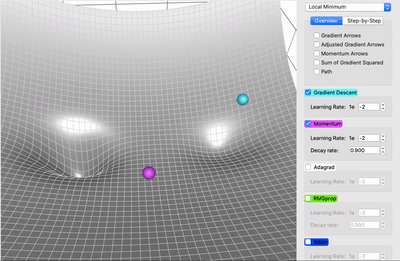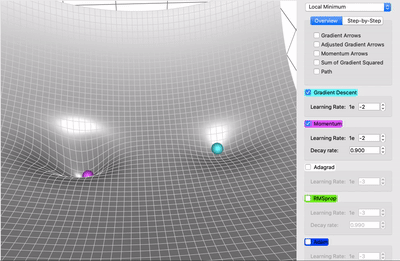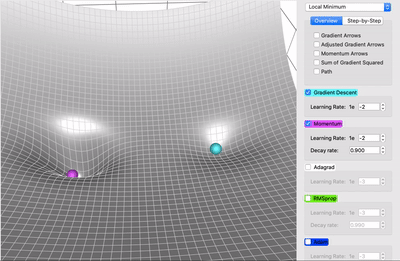
In the following visualization, purple represents SGD with Momentum, while light blue represents standard SGD. As shown, SGD with Momentum successfully reaches the global minimum, whereas standard SGD gets stuck in local minima.
However, momentum itself can sometimes be problematic. When the optimizer reaches the global minimum, excessive momentum may cause oscillations before stabilizing, leading to longer training times. Despite this, SGD with Momentum remains significantly faster than standard SGD and is widely used in optimization.
Papers archive 2025-07-28
30 shown of 144, newest first. Repository counts are the archive's code-links table. A Syntology line states what Syntology ran from that paper's harvested code; it is per sample and not a correctness claim.
-
AdamS: Momentum Itself Can Be A Normalizer for LLM Pretraining and Post-training 22 May 2025 · 1 repository · arXiv:2505.16363Syntology ran 0 of 1 samples · 1 unverified
-
Understanding Gradient Orthogonalization for Deep Learning via Non-Euclidean Trust-Region Optimization 16 Mar 2025 · 0 repositories · arXiv:2503.12645
-
Algorithmic Stability of Stochastic Gradient Descent with Momentum under Heavy-Tailed Noise 2 Feb 2025 · 0 repositories · arXiv:2502.00885
-
SOFIM: Stochastic Optimization Using Regularized Fisher Information Matrix 5 Mar 2024 · 0 repositories · arXiv:2403.02833
-
Should I try multiple optimizers when fine-tuning pre-trained Transformers for NLP tasks? Should I tune their hyperparameters? 10 Feb 2024 · 0 repositories · arXiv:2402.06948
-
Momentum Does Not Reduce Stochastic Noise in Stochastic Gradient Descent 4 Feb 2024 · 0 repositories · arXiv:2402.02325
-
AdaPlus: Integrating Nesterov Momentum and Precise Stepsize Adjustment on AdamW Basis 5 Sep 2023 · 1 repository · arXiv:2309.01966
-
When and Why Momentum Accelerates SGD:An Empirical Study 15 Jun 2023 · 0 repositories · arXiv:2306.09000
-
Fast Diffusion Model 12 Jun 2023 · 1 repository · arXiv:2306.06991Syntology ran 11 of 17 samples · 6 unverified
-
Layer-wise Adaptive Step-Sizes for Stochastic First-Order Methods for Deep Learning 23 May 2023 · 0 repositories · arXiv:2305.13664
-
MoMo: Momentum Models for Adaptive Learning Rates 12 May 2023 · 1 repository · arXiv:2305.07583Syntology ran 1 of 1 samples · 0 unverified
-
A view of mini-batch SGD via generating functions: conditions of convergence, phase transitions, benefit from negative momenta 22 Jun 2022 · 1 repository · arXiv:2206.11124Syntology ran 2 of 2 samples · 0 unverified
-
Computing the Variance of Shuffling Stochastic Gradient Algorithms via Power Spectral Density Analysis 1 Jun 2022 · 1 repository · arXiv:2206.00632
-
An Adaptive Gradient Method with Energy and Momentum 23 Mar 2022 · 1 repository · arXiv:2203.12191
-
Does Momentum Change the Implicit Regularization on Separable Data? 8 Oct 2021 · 0 repositories · arXiv:2110.03891
-
Using a one dimensional parabolic model of the full-batch loss to estimate learning rates during training 31 Aug 2021 · 1 repository · arXiv:2108.13880
-
On the Hyperparameters in Stochastic Gradient Descent with Momentum 9 Aug 2021 · 0 repositories · arXiv:2108.03947
-
A New Adaptive Gradient Method with Gradient Decomposition 18 Jul 2021 · 0 repositories · arXiv:2107.08377
-
LRTuner: A Learning Rate Tuner for Deep Neural Networks 30 May 2021 · 2 repositories · arXiv:2105.14526
-
Fast Federated Learning by Balancing Communication Trade-Offs 23 May 2021 · 2 repositories · arXiv:2105.11028
-
Positive-Negative Momentum: Manipulating Stochastic Gradient Noise to Improve Generalization 31 Mar 2021 · 1 repository · arXiv:2103.17182Syntology ran 1 of 1 samples · 0 unverified
-
Bottleneck Transformers for Visual Recognition 27 Jan 2021 · 13 repositories · arXiv:2101.11605Syntology ran 26 of 49 samples · 23 unverified · 8 pointer-only (licence)
-
The Ikshana Hypothesis of Human Scene Understanding 21 Jan 2021 · 2 repositories · arXiv:2101.10837
-
RepVGG: Making VGG-style ConvNets Great Again 11 Jan 2021 · 25 repositories · arXiv:2101.03697Syntology ran 13 of 16 samples · 3 unverified · 6 pointer-only (licence)
-
MAGNeto: An Efficient Deep Learning Method for the Extractive Tags Summarization Problem 9 Nov 2020 · 1 repository · arXiv:2011.04349
-
Dual Averaging is Surprisingly Effective for Deep Learning Optimization 20 Oct 2020 · 0 repositories · arXiv:2010.10502
-
AEGD: Adaptive Gradient Descent with Energy 10 Oct 2020 · 1 repository · arXiv:2010.05109
-
Regularizing Neural Networks via Adversarial Model Perturbation 10 Oct 2020 · 1 repository · arXiv:2010.04925Syntology ran 0 of 12 samples · 12 unverified
-
Momentum via Primal Averaging: Theoretical Insights and Learning Rate Schedules for Non-Convex Optimization 1 Oct 2020 · 1 repository · arXiv:2010.00406
-
Optimization of Graph Neural Networks with Natural Gradient Descent 21 Aug 2020 · 1 repository · arXiv:2008.09624
Tasks archive 2025-07-28
20 shown of 137 tasks the archive attaches to papers tagged with this method, by distinct papers. A task without a page in the catalog is plain text.
Usage over time archive 2025-07-28
Components: the archive holds no method-to-method composition, so PwC's Components table cannot be rebuilt; the Papers list carries no Results column for the same reason (the archive does not join its leaderboard rows to method tags).
Categories archive 2025-07-28
Report a problem or propose a change · a person checks every report against the paper or source before anything changes; decisions are listed on /corrections