Datasets › Chinese Gigaword
Chinese Gigaword
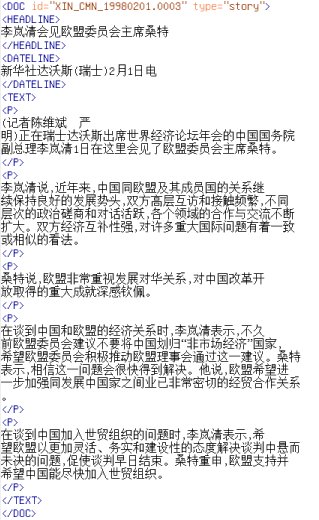
Chinese Gigaword corpus consists of 2.2M of headline-document pairs of news stories covering over 284 months from two Chinese newspapers, namely the Xinhua News Agency of China (XIN) and the Central News Agency of Taiwan (CNA).
Source: Order-Preserving Abstractive Summarization for Spoken Content Based on Connectionist Temporal Classification Image Source: https://catalog.ldc.upenn.edu/desc/addenda/LDC2011T13.jpg
Benchmarks archive 2025-07-28
No leaderboard in the archive resolves to this dataset.
Papers archive 2025-07-28
No paper in the archive has a leaderboard row on this dataset; the archive counts 2 papers for it but never published that list.
Dataset loaders archive 2025-07-28
No loader listed in the archive.
Tasks archive 2025-07-28
License archive 2025-07-28
Modalities archive 2025-07-28
Languages archive 2025-07-28
Variants archive 2025-07-28
- Chinese Gigaword
1 variant name, as the archive lists them.
Report a problem or propose a change · a person checks every report against the paper or source before anything changes; decisions are listed on /corrections